 Walid Karray
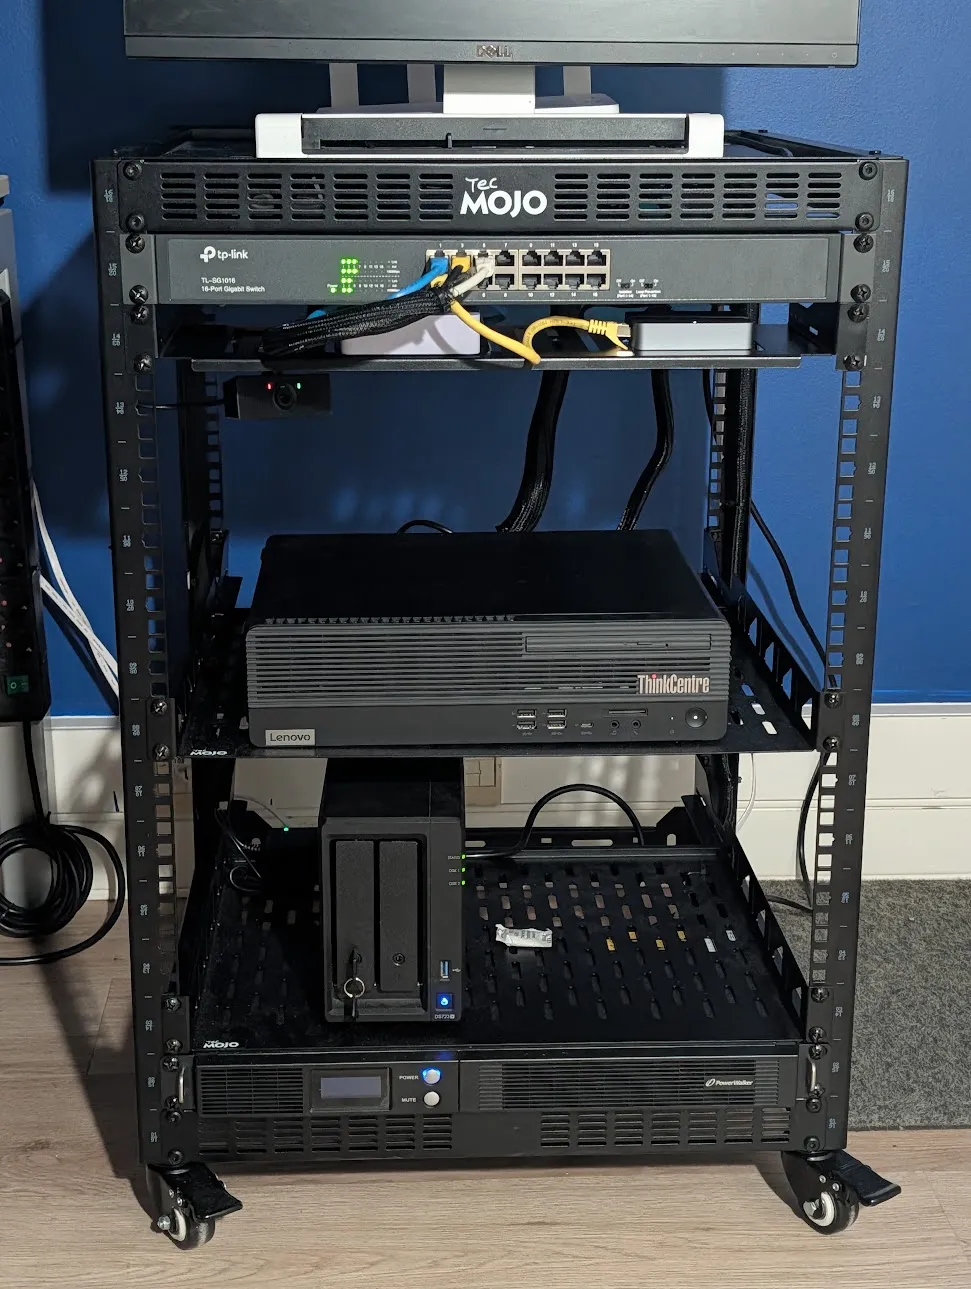
I carry a MacBook Pro, but I don’t really work on it. My work happens in this rack, on two dev boxes where my coding agents run too, next to everything I use daily: Jellyfin, Paperless, my notes, my bookmarks and a local LLM. The rack serves nobody but me, and nothing in it is reachable from the internet.
Most of it runs on one office PC with Proxmox, and a push to main deploys everything but the hypervisor and the cluster’s two nodes, which I apply by hand. Here is how it fits together, from the hardware up.
The rack
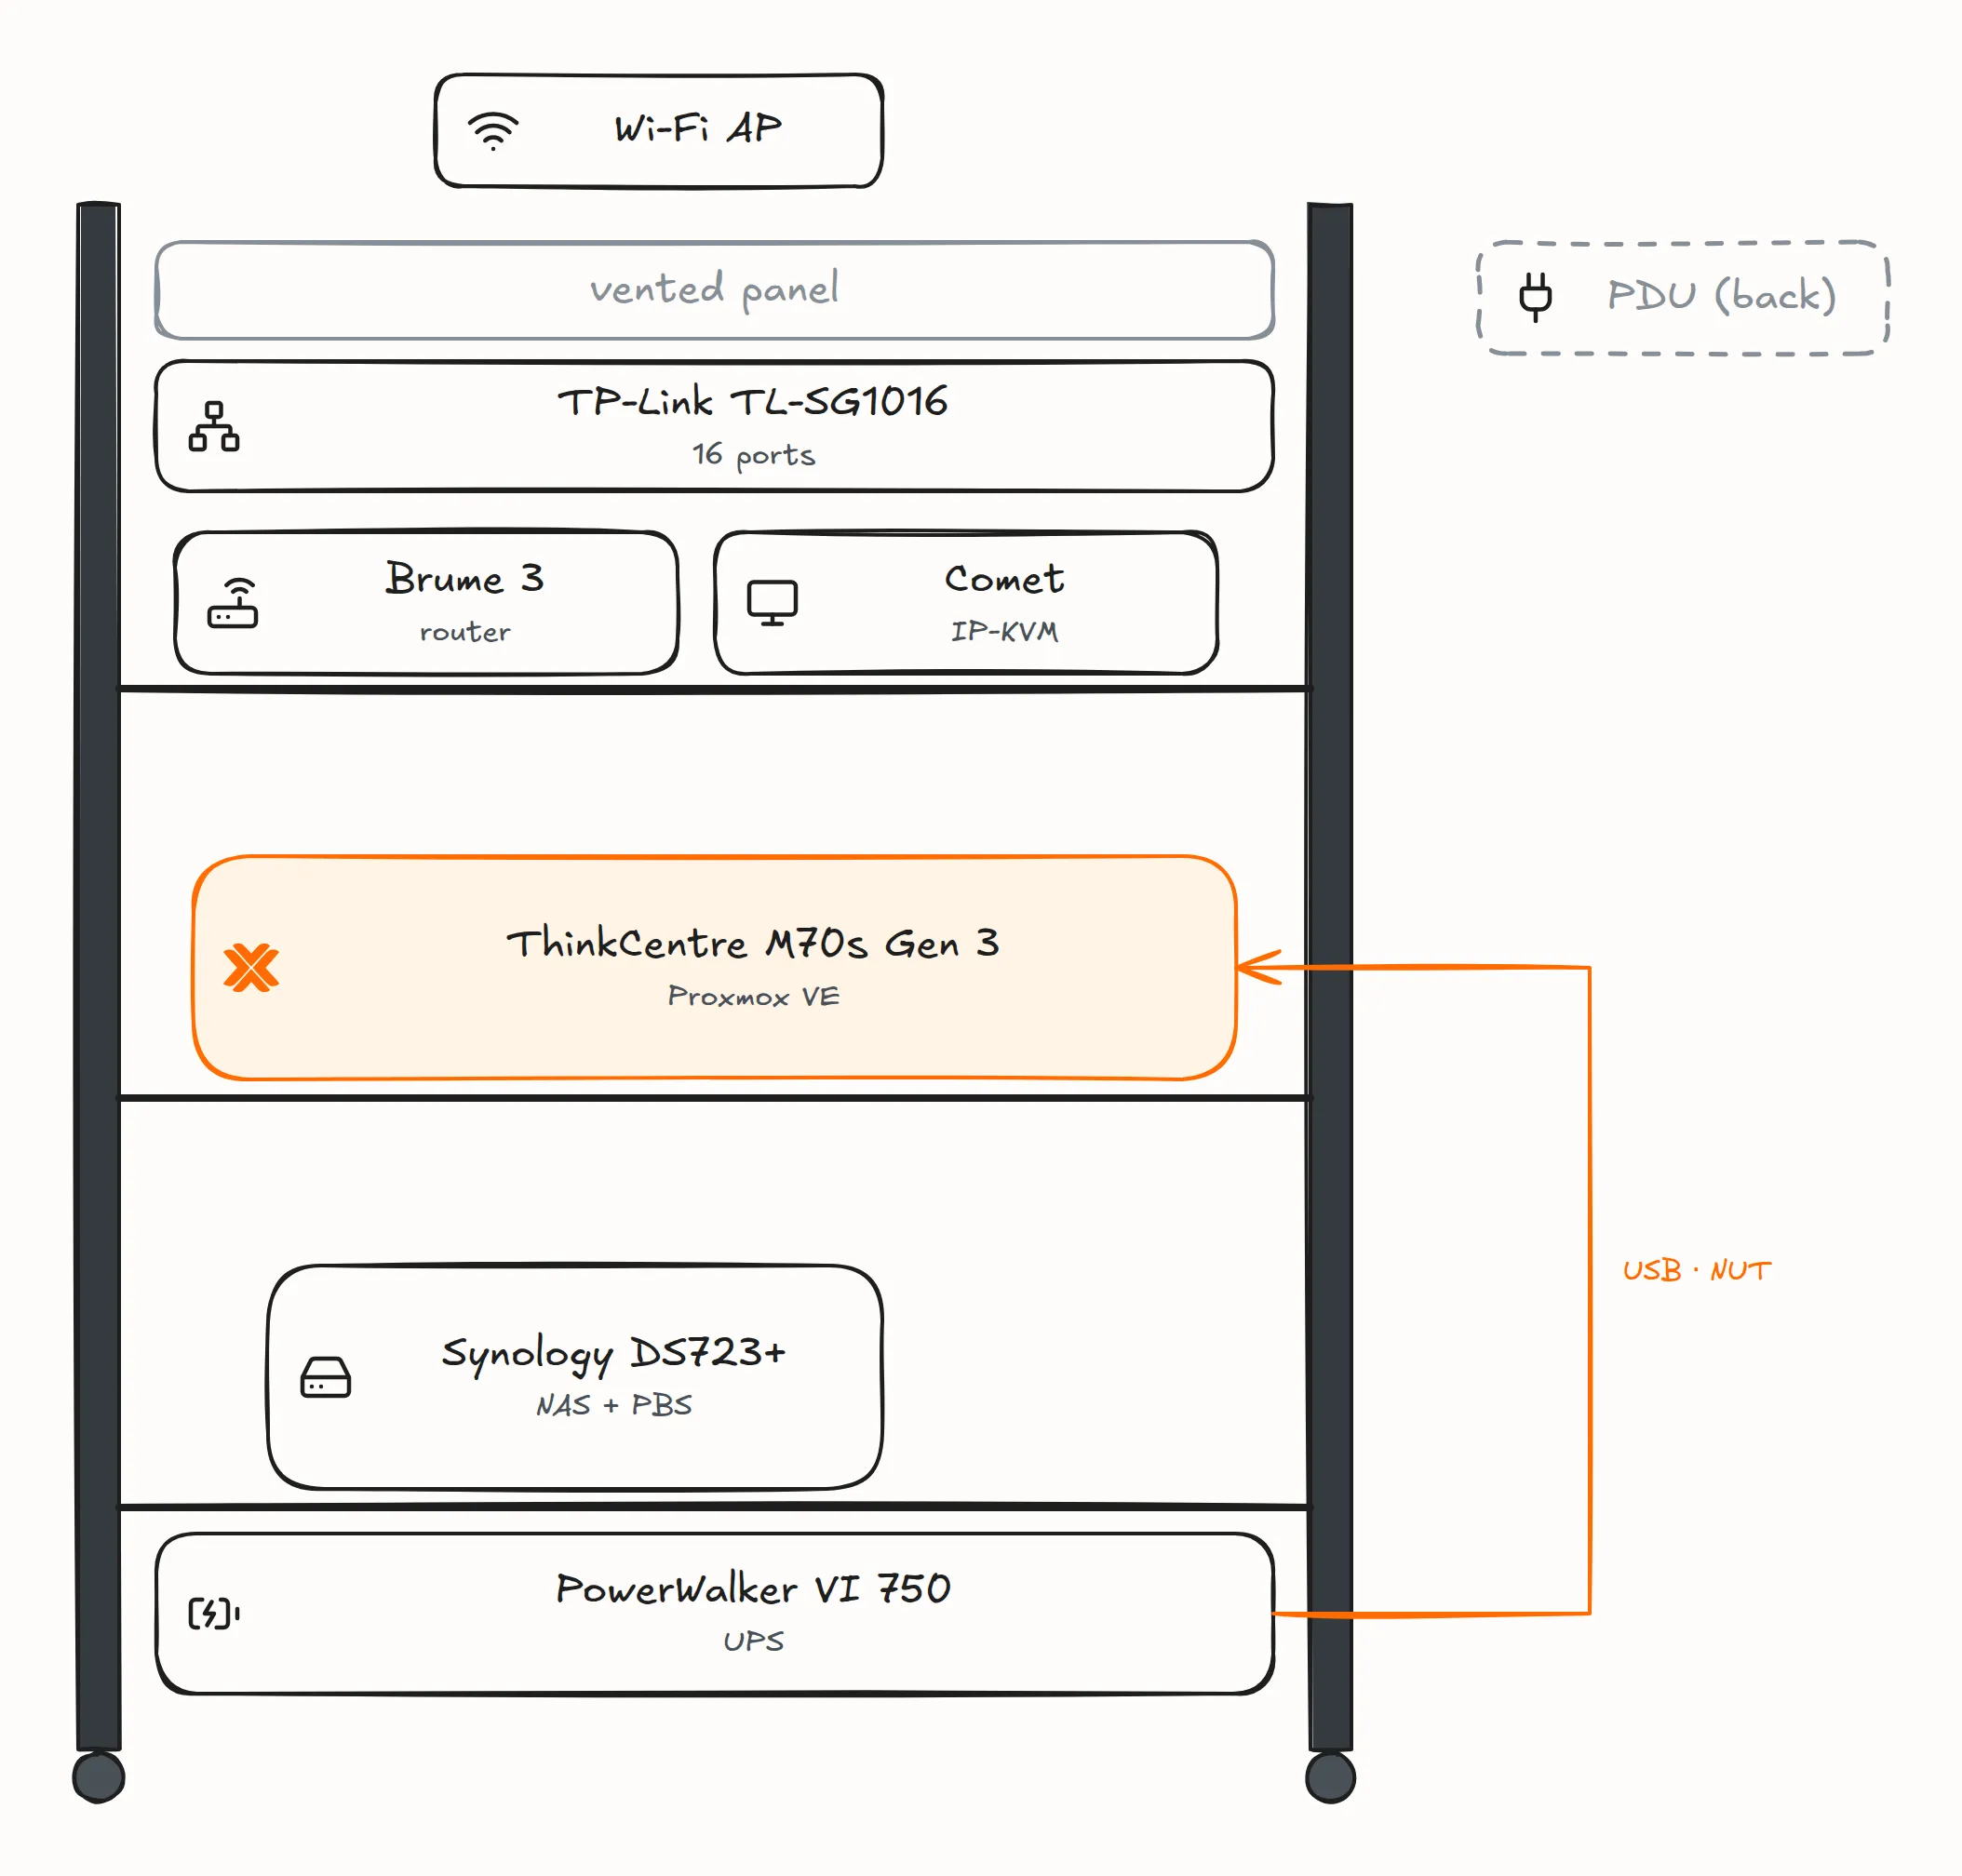
The hypervisor is a Lenovo ThinkCentre M70s Gen 3: an Intel Core i7-12700 (12 cores, 20 threads), 64 GB of DDR4 without ECC, a 512 GB NVMe drive for the system and a 1 TB SATA SSD for the guests, with an Intel I210-T1 card as the uplink. Being an office PC, it has no remote console like iDRAC or IPMI, so a GL.iNet Comet (GL-RM1) IP-KVM sits on its HDMI and USB ports.
Around it, in a Tecmojo 16U open-frame rack:
- a Synology DS723+ with one SSD and one HDD, each its own volume, running Proxmox Backup Server (PBS);
- a GL.iNet Brume 3 (GL-MT5000), a plain home router that the lab uses as its uplink and as a second DNS resolver for the tailnet;
- a TP-Link TL-SG1016, an unmanaged 16-port switch;
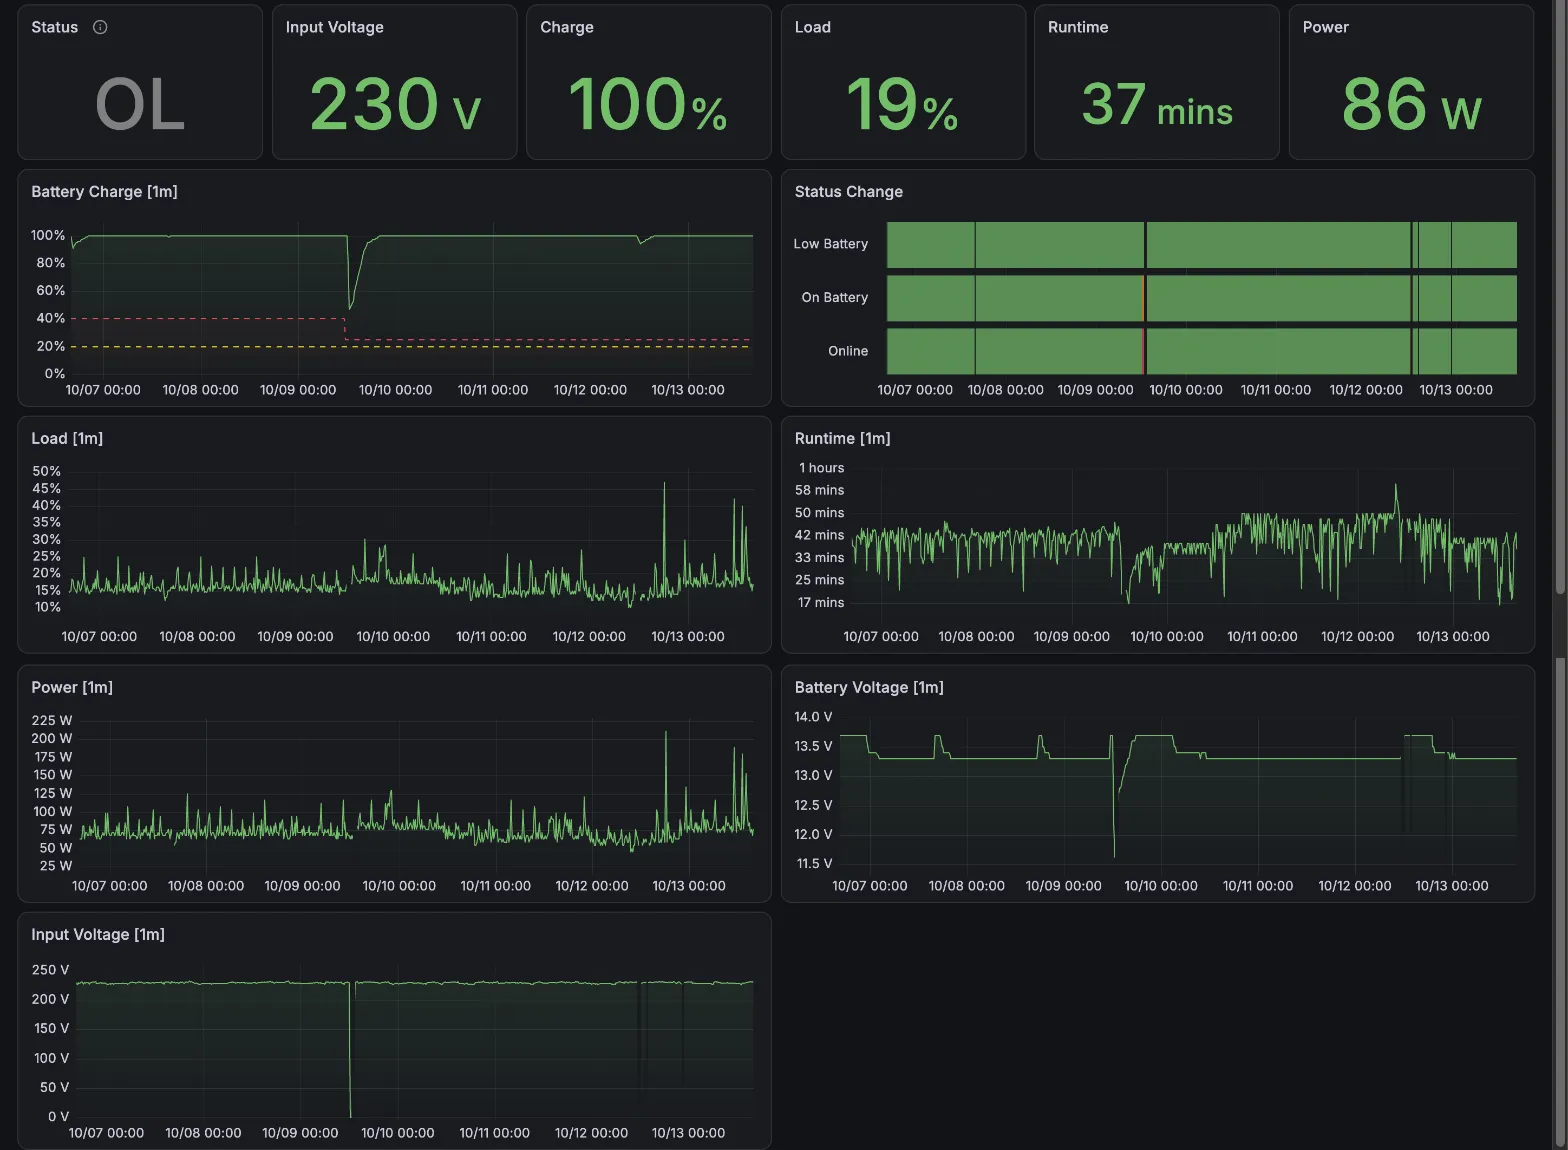
- a PowerWalker VI 750 R1U UPS on the hypervisor’s USB, served by NUT, which shuts down the hypervisor and the NAS on a power cut. What it gets wrong is in My UPS Lies.
The UPS puts the draw at about 80 W on average and 250 W at peak. That is its load percentage times its 450 W rating, so a rough figure, but at France’s regulated rate of €0.20/kWh, it comes to about €140 a year, VAT included.
What runs on it
Five rules, written at the top of the lab’s docs, decide most of what follows:
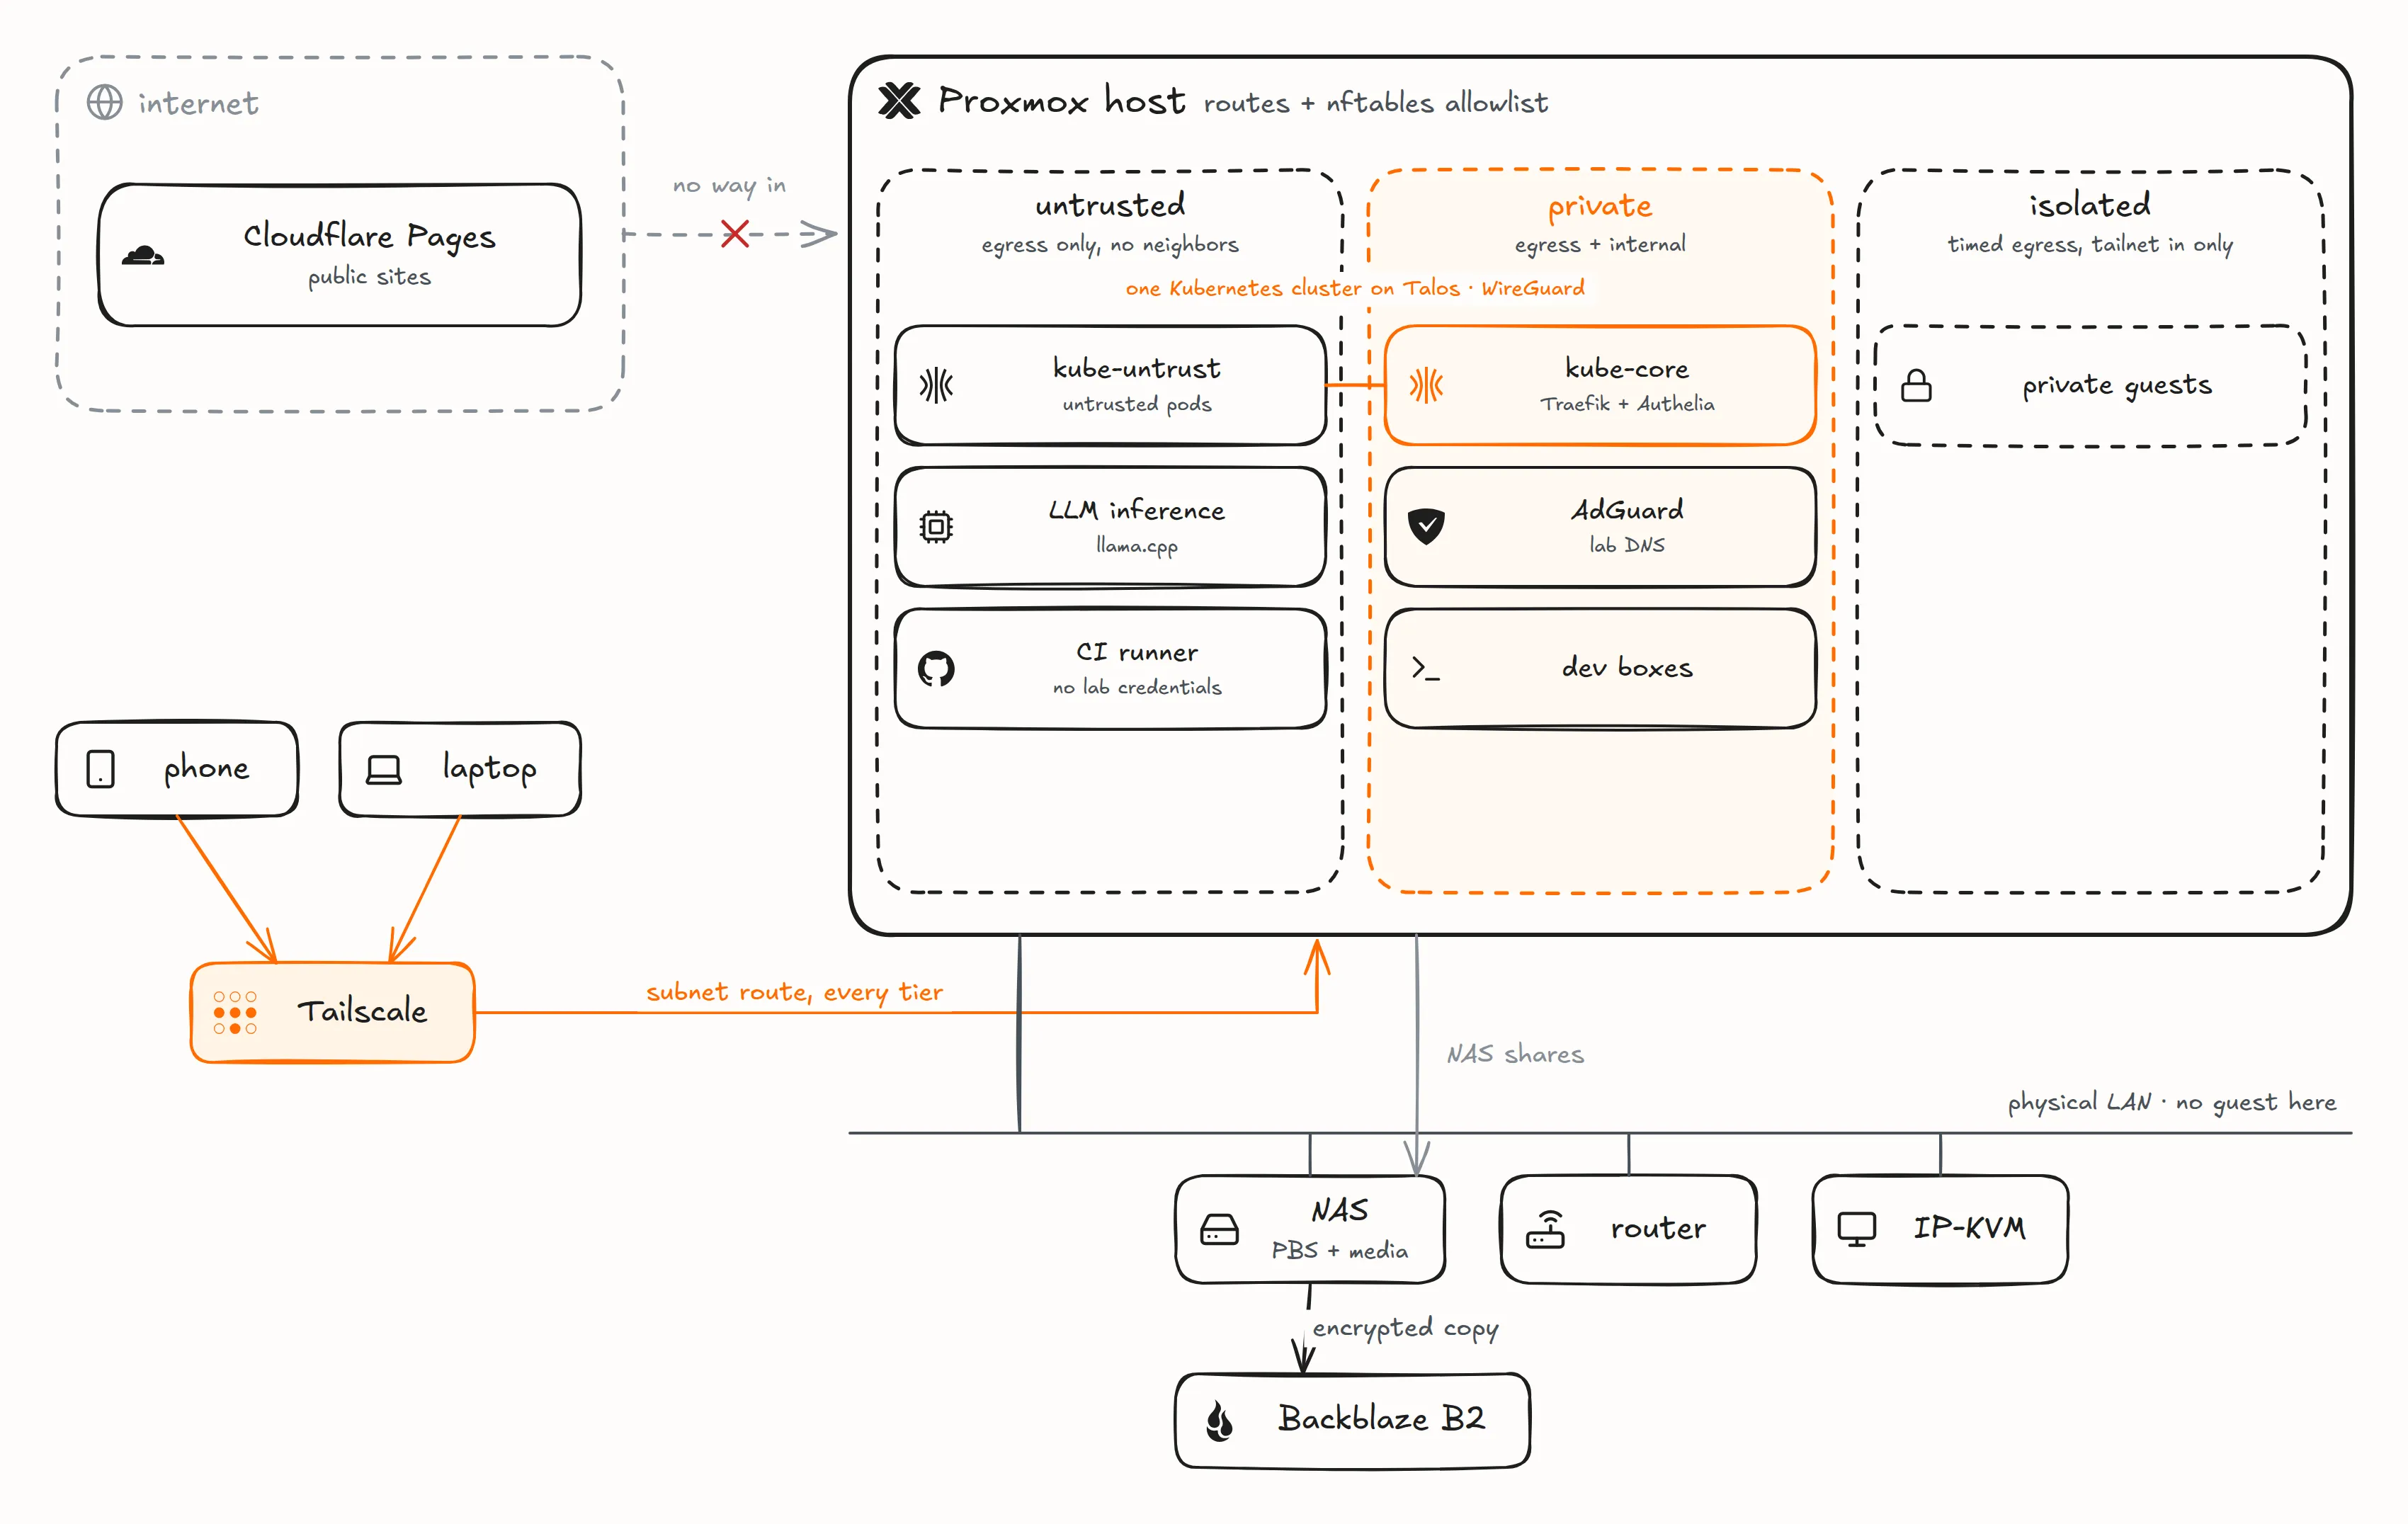
- Nothing public reaches the lab: no inbound port, no tunnel. The public sites, this blog included, are Cloudflare Pages projects.
- Private by default: lab names resolve to a private address, reached through Tailscale.
- One front door: Traefik terminates TLS for every service, and Authelia puts a single sign-on in front of it.
- No guest on the physical LAN: only the hypervisor has an address there.
- Everything is in git, secrets included as ciphertext, and a push to
mainis live within minutes.
Rule 1 is about inbound traffic. The door that does matter is my GitHub account: whatever lands on main deploys into the lab, an upstream image that Renovate merges by digest included, and the deploy post says how far that is trusted.
On Proxmox VE, most services I self-host run in one Kubernetes cluster made of two VMs. A cluster gives me one deploy loop, one route table and one isolation model: a namespace (Kubernetes’ unit for grouping an app), the network tier it belongs to (more on tiers below) and its network policies, enforced per pod. Separate container hosts would each need their own deploy agent and log agent, and their containers would all leave under the host’s one address, where a firewall can’t tell them apart.
The nodes run Talos Linux, an OS that runs Kubernetes and nothing else: no SSH, no shell, no package manager. A node is its machine config, generated from the repository and applied through Talos’s API, and an upgrade swaps the whole system image and reboots. Nothing on a node is edited by hand, and just talos check compares a node’s running config with the repository. Each node has a second disk where every persistent volume lives, so reinstalling the OS never touches the data.
The two nodes are split by trust, not by load. kube-core carries the control plane, Traefik, Authelia and every app I vouch for, each owning its database when it needs one: Paperless, Outline, linkding, Open WebUI, Presto (my own time tracker), the monitoring stack and more. The cluster runs about twenty apps and sixty pods in all. kube-untrust gets what handles traffic nobody vouches for, like downloads through a commercial VPN and a remote browser, so a process that escapes one of those apps finds no Authelia, no database and no key. There is one control plane and no high availability; the targets at the end of this post don’t call for it.
Anything that runs containers, or code from a pull request, gets a VM with a kernel of its own: the two cluster nodes and the CI runner. An LXC container shares the host’s kernel. Proxmox doesn’t support running a container runtime inside one, and under AppArmor a containerd security fix breaks it. Most other guests are lighter unprivileged LXC containers: among them AdGuard Home as the DNS for my devices, local LLM inference with llama.cpp and the two dev boxes. Three more guests are Windows VMs. AdGuard stays out of the cluster on purpose: there, a node restart, an image pull or a failed reconcile would take DNS down with it.
The network is split into tiers, like a cloud VPC
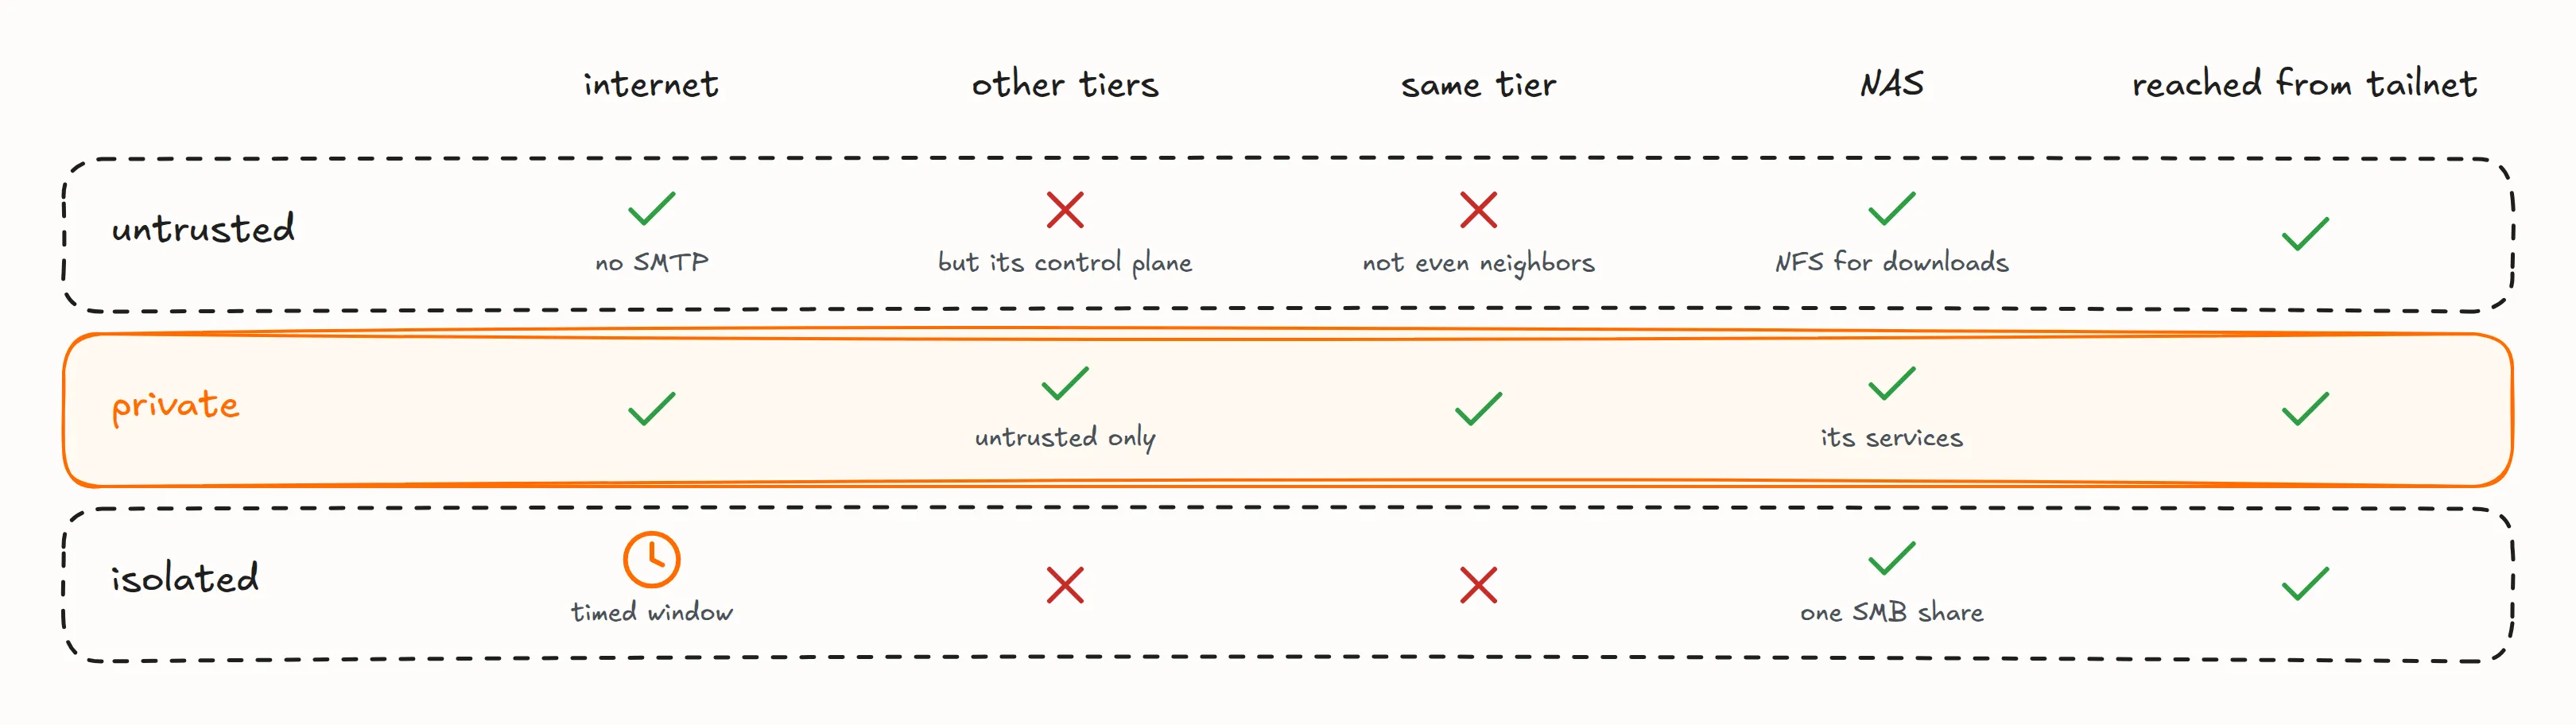
Behind the home router, the hypervisor routes everything, without NAT: the router is the only NAT, out to the internet, and routes the tiers back to the hypervisor, so the NAS sees each guest’s own address. Each guest sits on a Linux bridge, and each bridge belongs to a tier:
- physical LAN: the hypervisor, the NAS, the router and the IP-KVM, never a guest;
- untrusted: the internet, and inside the lab nothing but its cluster’s control plane and one NFS share on the NAS for downloads, not even its neighbors.
kube-untrustlives here, with the LLM box, because it loads models from the internet, and the CI runner, because it runs whatever a pull request says; - private: the internet, the untrusted tier and the NAS’s services, one port per service.
kube-core, AdGuard and the dev boxes live here; - isolated: no internet outside a timed window, nothing gets in but the tailnet, and nothing goes out but its declared endpoints: today one SMB share on the NAS, which a Proxmox firewall rule narrows to the one guest that uses it.
The firewall is one nftables allowlist on the hypervisor. It reads the matrix one tier at a time, one line per flow it opens, and refuses and logs anything not listed. Tiers match bridges by name pattern, so a new bridge inherits its tier’s rules without touching the firewall. After a firewall change, I run a probe that checks the whole matrix above. The guests that guard something also get their own Proxmox firewall rules, the equivalent of a cloud’s security groups. The guests themselves resolve DNS through public resolvers, never through AdGuard. IPv6 is dropped on every segment, IPv6 tunneled inside IPv4 included.
The tiers carry on inside the cluster. Each node sits on its tier’s network and carries its tier as a taint, and each namespace accepts only its own tier’s toleration, so a pod lands on its tier’s node or nowhere. A tier is a taint and never a label, because a kubelet, the agent on each node, can relabel its own node but can’t change its taints: a compromised worker can’t pull a private pod onto itself. Cilium is the cluster’s network. It replaces kube-proxy, encrypts traffic between the two nodes with WireGuard, and enforces the network policies: every app namespace starts from deny-all and opens only the flows it needs, and its pods run under the restricted Pod Security profile unless a commented exception says otherwise.
Tailscale is the only way in from the network
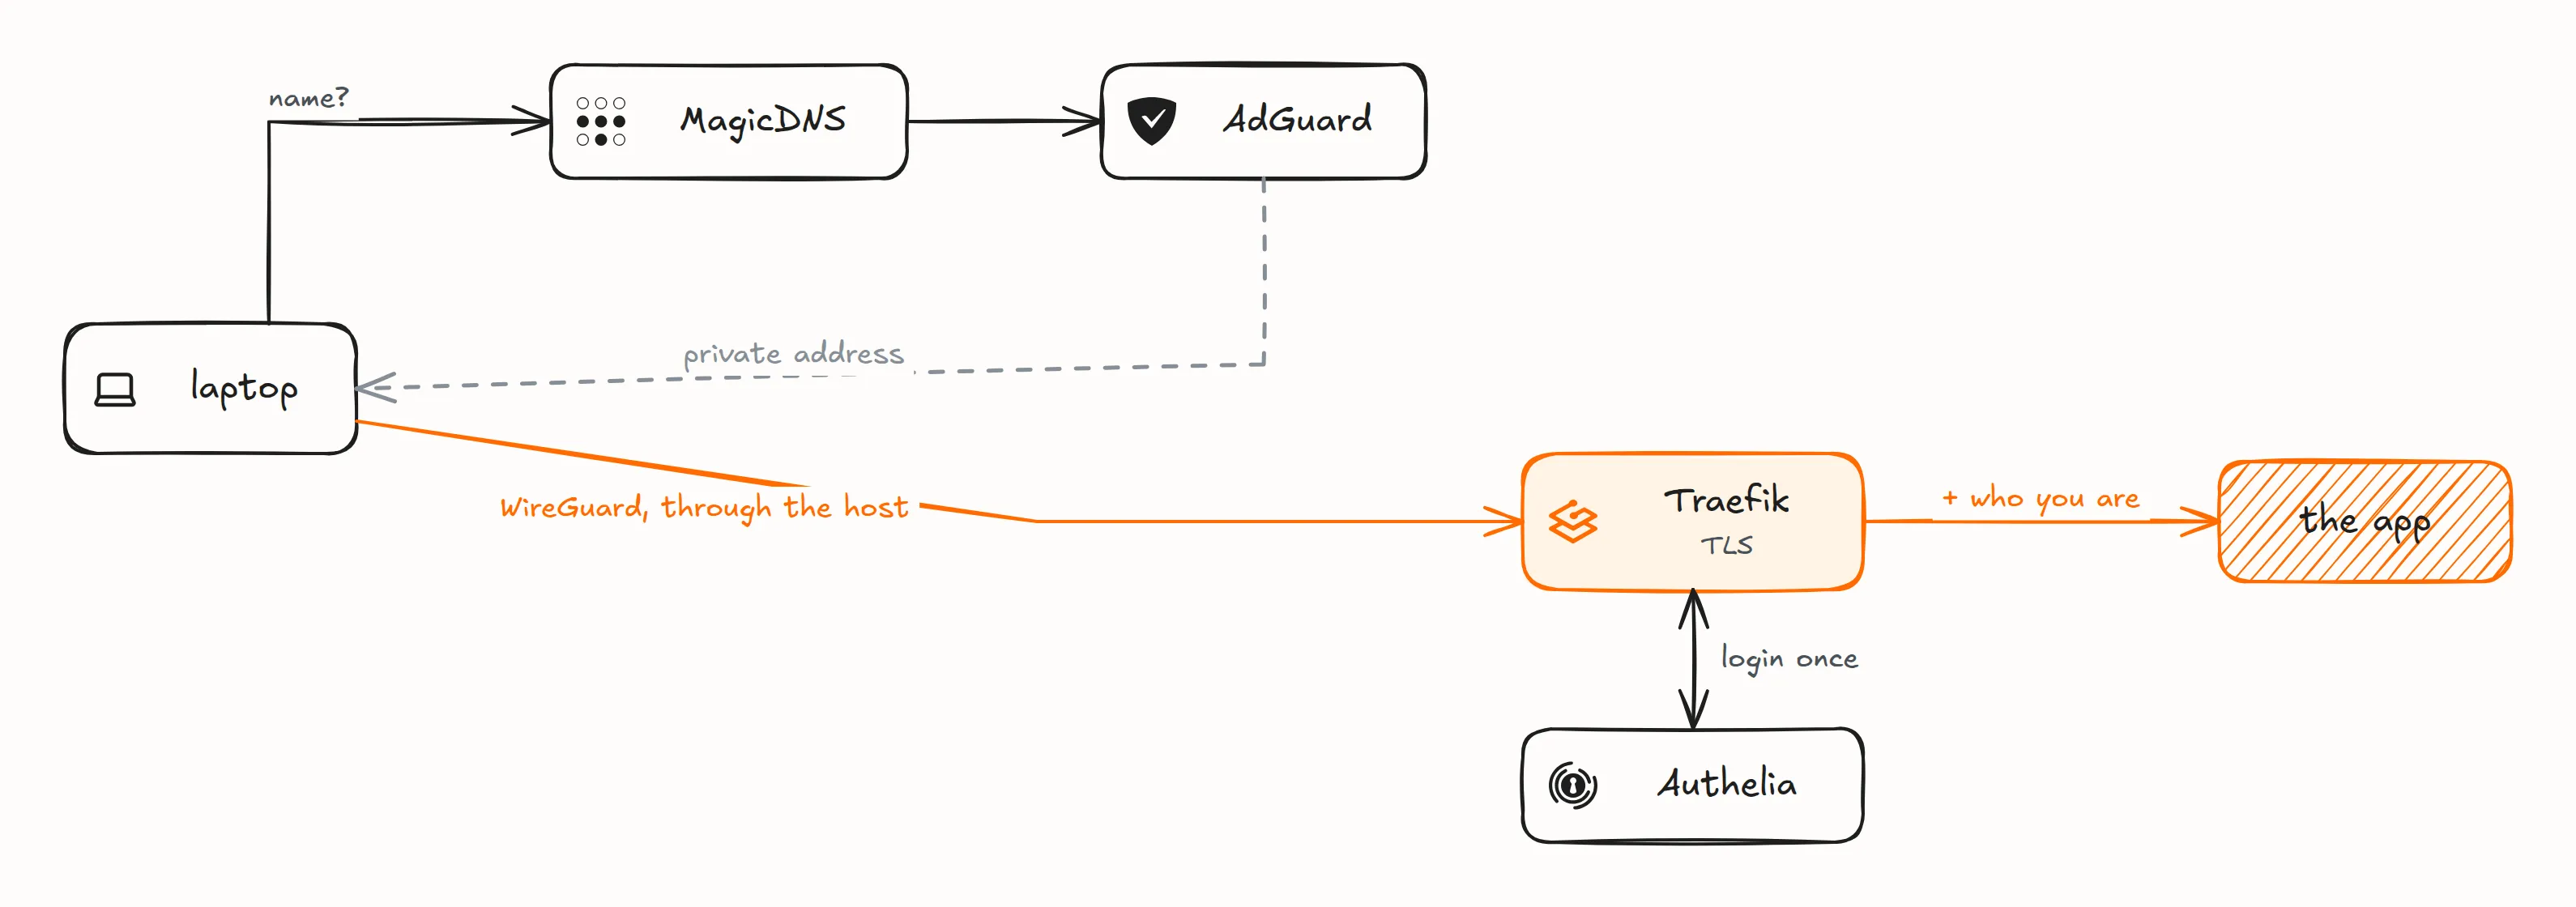
No guest runs Tailscale. The hypervisor advertises a subnet route into the lab, and my laptop and phone reach every guest through it. That keeps a single door and no Tailscale client to maintain in each guest. The tailnet is only my way in, never a path inside the lab: traffic between the lab and the rack’s machines, like the backups and the NAS’s UPS client, goes over the LAN through the hypervisor, and none of it depends on Tailscale running.
Opening an app takes one lookup and one login: MagicDNS sends lab names to AdGuard, Traefik terminates TLS on kube-core, and Authelia checks who I am once, in front of the app or as its OpenID Connect provider. Traefik routes to the apps through Gateway API routes, and to a few machines outside the cluster. Its certificate is a single wildcard from cert-manager, validated through DNS, so no HTTP endpoint is exposed and no service name ends up in the public certificate logs. The public sites never get that far; they stop at Cloudflare.
Every other lookup from my devices goes to two resolvers at once, the AdGuard guest and an AdGuard Home on the Brume 3, and Tailscale takes the first answer. Both have the same blocklist and upstreams. With AdGuard alone, the hypervisor going down would take the whole internet away from my laptop; a public resolver would avoid that, but it would see every query from my devices.
Names and tags follow one convention
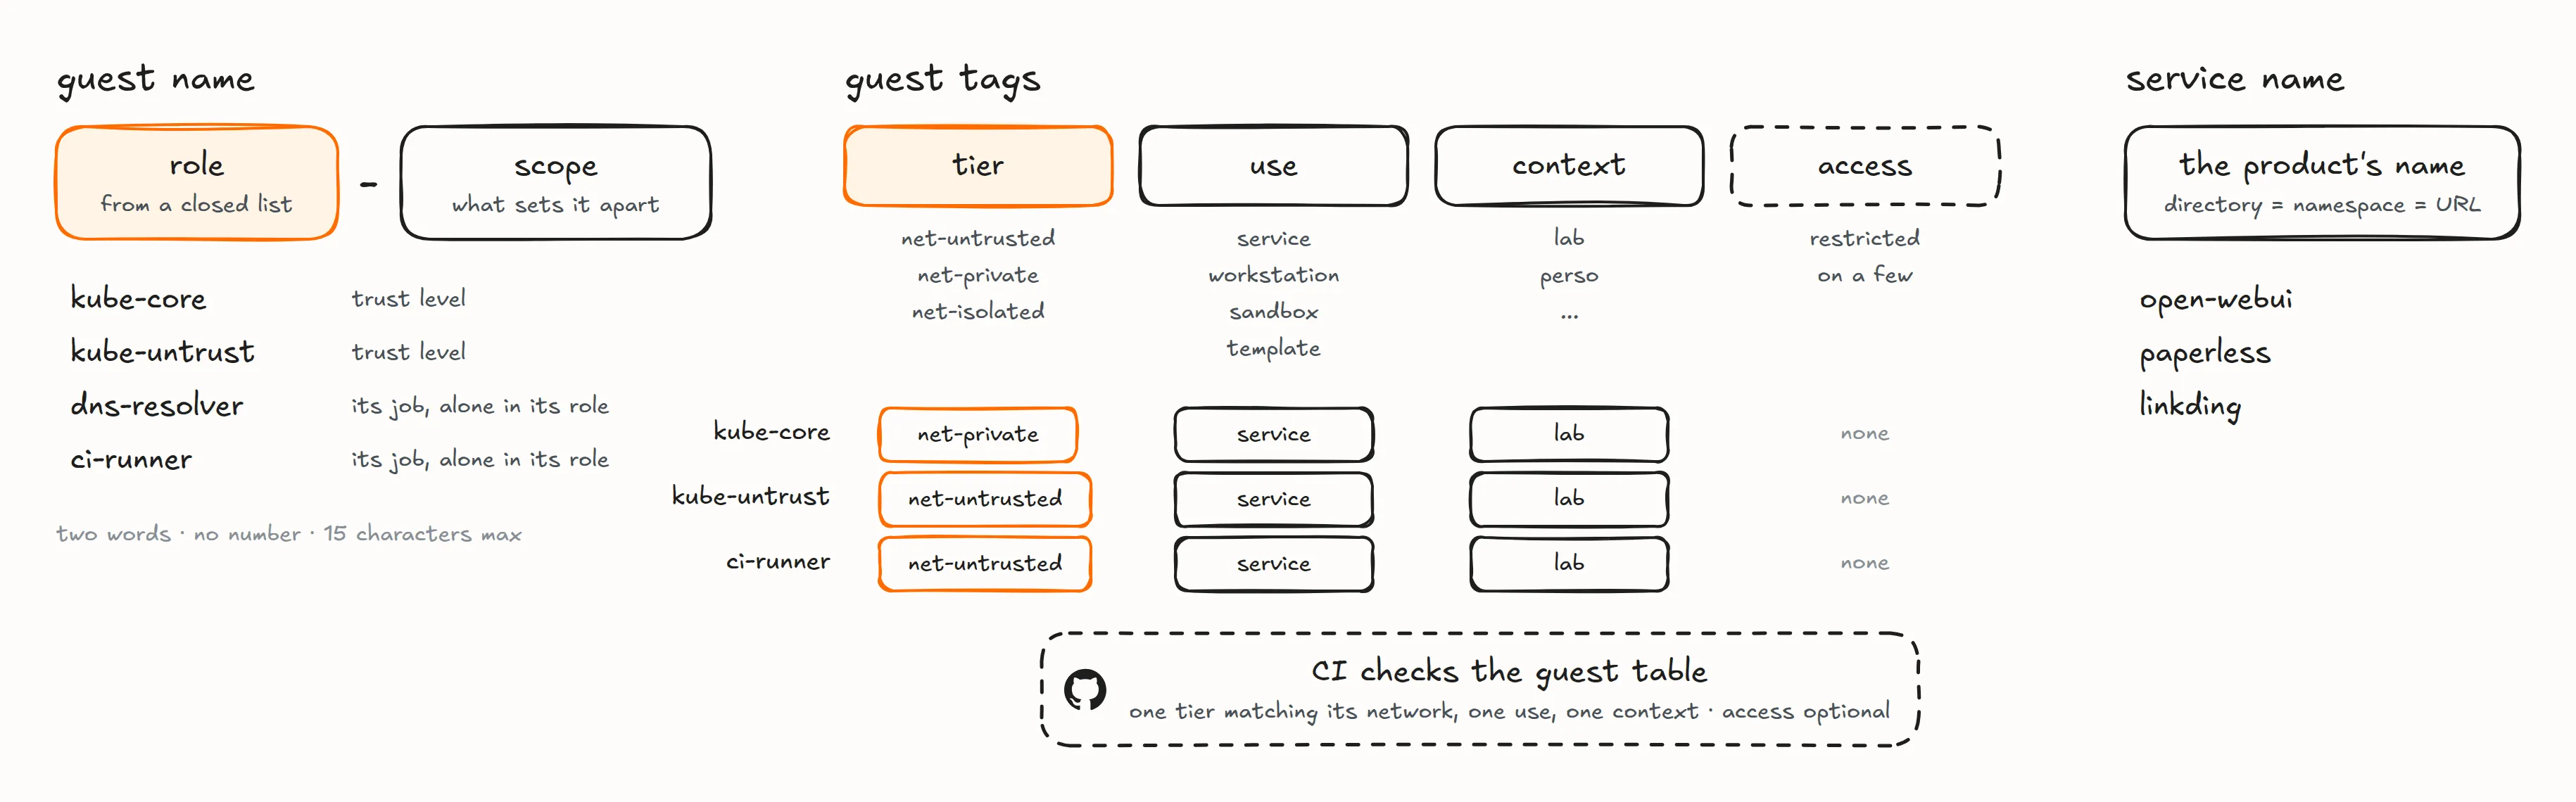
A guest’s name is two words: a role from a closed list, and what sets it apart. No numbers and no brand names, because the name is what shows up in an alert at 3 a.m., and kube-untrust says what broke. What the name doesn’t say goes into three Proxmox tags, tier, use and context, plus restricted on a guest closed to my coding agents. The docs list every guest’s tags, and CI fails if that list gives a guest anything but one tier, one use and one context, or a tier that doesn’t match its address. It checks the docs, not the live tags.
Apps keep their product’s name: Open WebUI’s directory, namespace and URL are all open-webui. An app that bundles several products under one lifecycle is named for what ties them, like monitoring, but each of its URLs keeps its product’s name, like grafana.
A push to main is the deployment
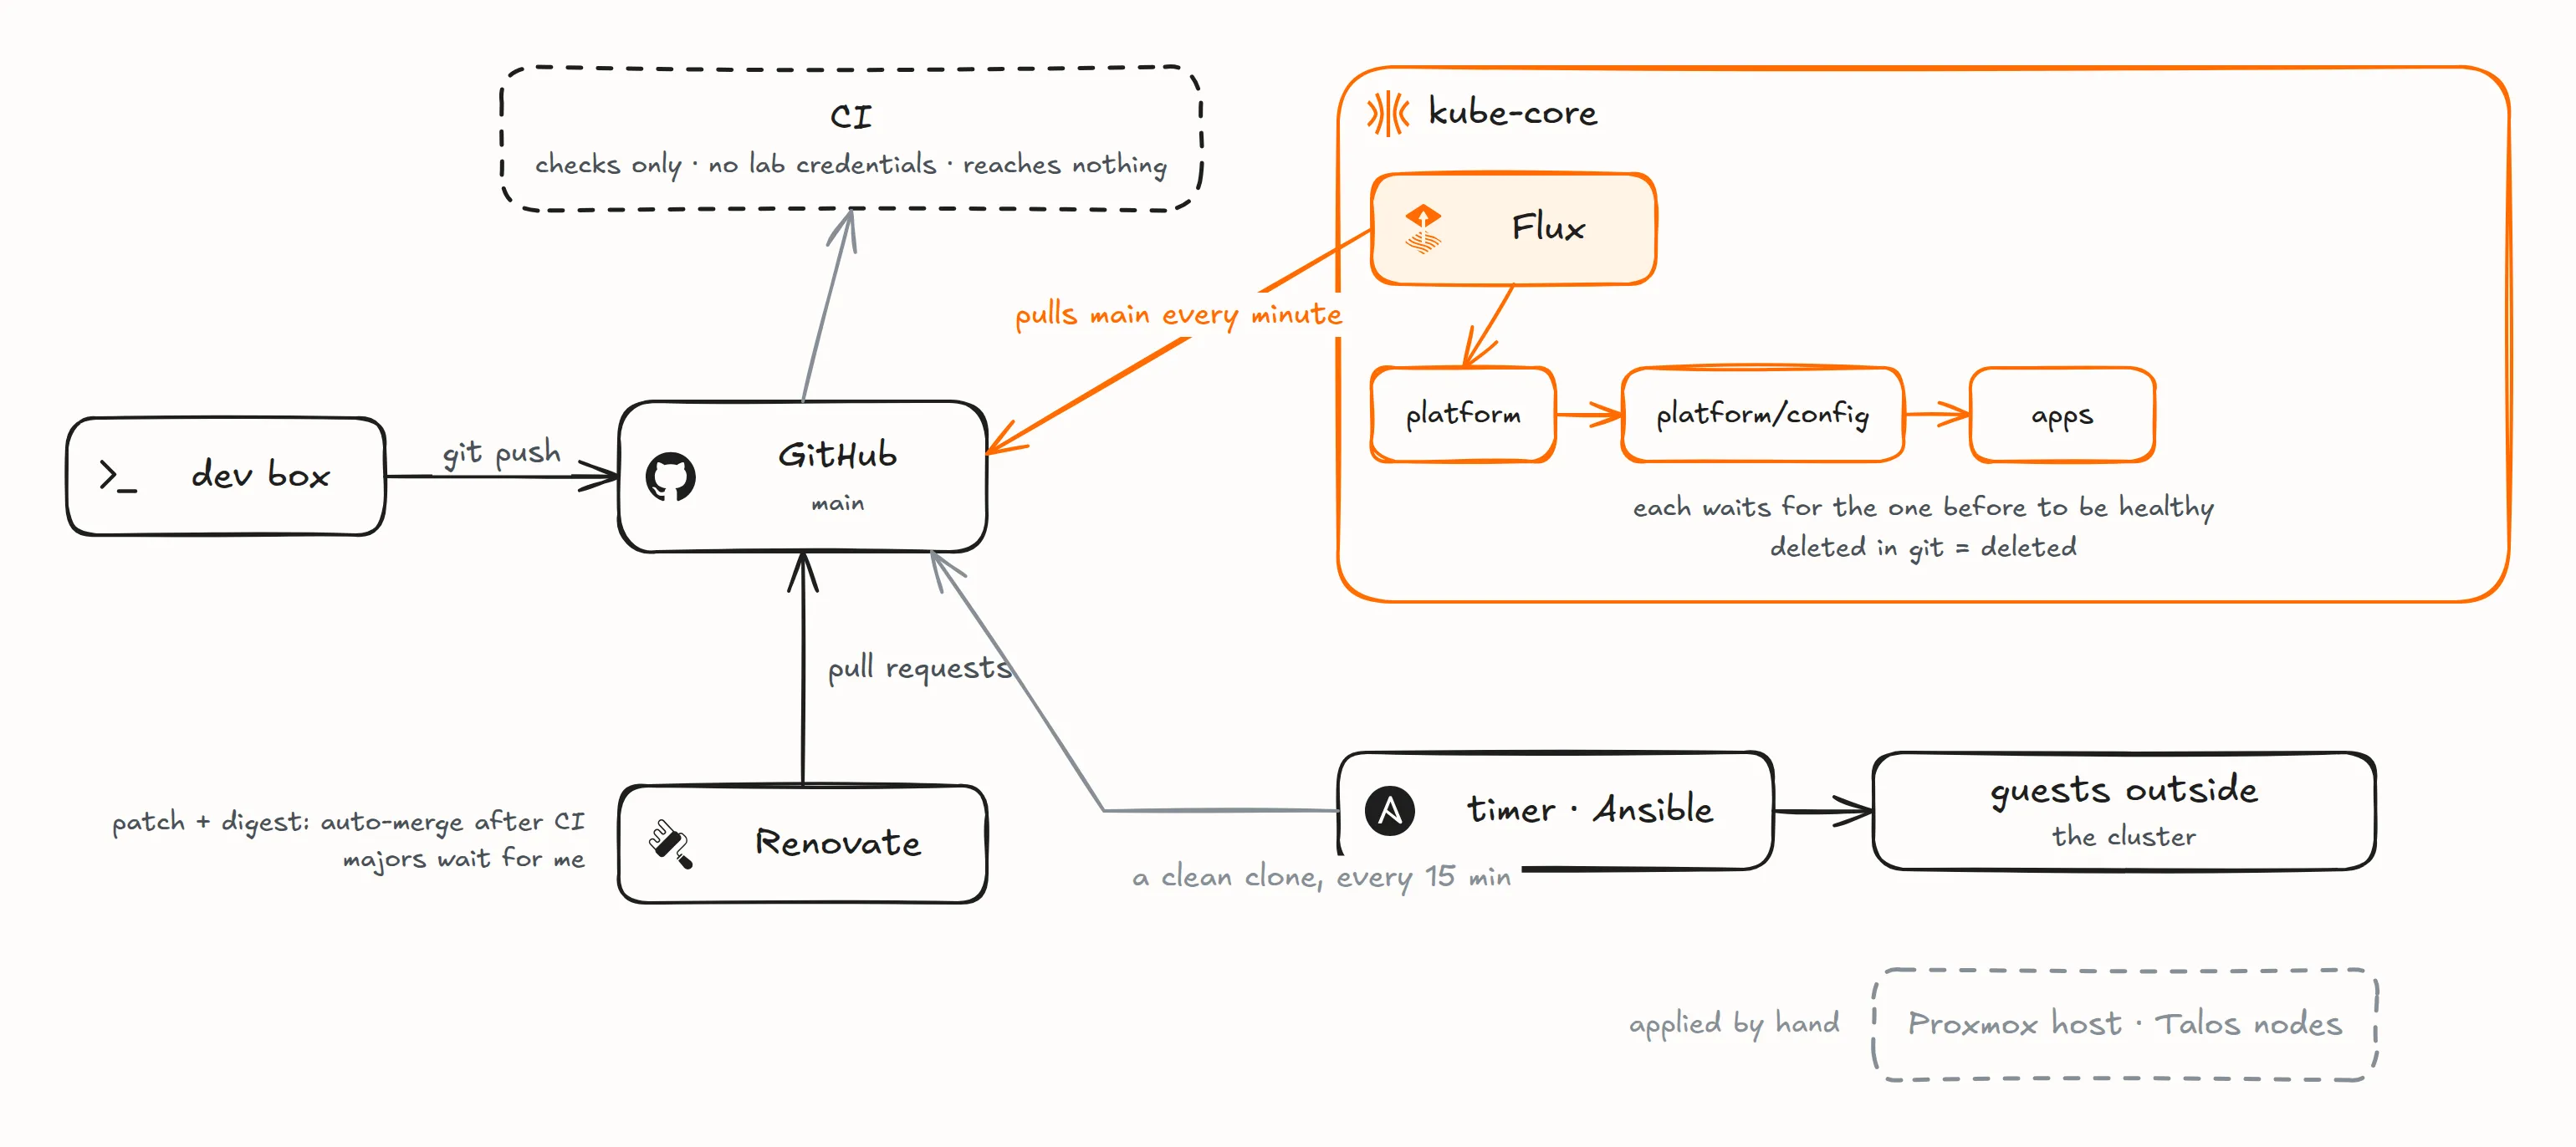
One private repository holds everything: the Kubernetes manifests, the Talos config, the Ansible roles, Terraform for Cloudflare, a copy of the Tailscale policy and the docs. CI runs on the runner in the untrusted tier. It renders every manifest and validates it against its schema, checks the repository’s own rules (every namespace has exactly one tier, no manifest writes a toleration or opens a host port), validates the Talos configs, and scans for secrets with gitleaks. It holds no credential into the lab, and it runs alongside the deploy, not before it: a red CI tells me to revert, it doesn’t stop anything. Nothing outside the lab pushes a deployment; two loops inside it pull main.
The first loop is Flux, running in the cluster on kube-core. It polls main every minute and applies the kubernetes/ directory: first Flux itself, whose own manifests live there too. Flux’s own step creates the other three: the platform (Cilium, CoreDNS, Traefik, cert-manager, storage), then the platform’s configuration, then the apps, each of the last two waiting for the one before to be healthy, not just applied. A broken platform holds the apps back instead of leaving them half applied. Whatever is deleted from git is deleted from the cluster, and anything changed by hand is put back within ten minutes. I picked Flux over Argo CD, which needs a plugin to read SOPS and brings a UI, a Redis and its own login, for one person who works from a terminal. Its own post covers the deploy in detail.
The second loop keeps the machines outside the cluster in line. Every 15 minutes, a timer applies the Ansible roles to the guests from a clean clone of main, so anything changed by hand is reverted at the next run. On the dev boxes it skips the two editor servers, since restarting them would kill my open terminals. Two things are never on a timer. The hypervisor, because that would be a standing root path into it; I apply its roles by hand. And the Talos nodes, which change rarely and have nothing to drift from; I apply their config and their upgrades by hand too.
Renovate keeps the versions moving, on weekends, with one pull request per app, since an app’s directory is what Flux applies and what I revert. Patch and digest bumps merge themselves once CI is green, and major versions wait for my approval on Renovate’s dependency dashboard. CI doesn’t run the new image, so a bad one shows up as a Flux object that stays not ready, which mails me after ten minutes, and I revert. Flux waits for the apps’ pods to be healthy, so a pod that never starts counts as a failed deploy too. A container that later stops answering its probe is restarted by Kubernetes; the probe is meant to test the process itself, never a dependency. Undoing anything is git revert and a push, and a bad commit reaches the machines on its own just the same.
Secrets live in git, sealed to the cluster
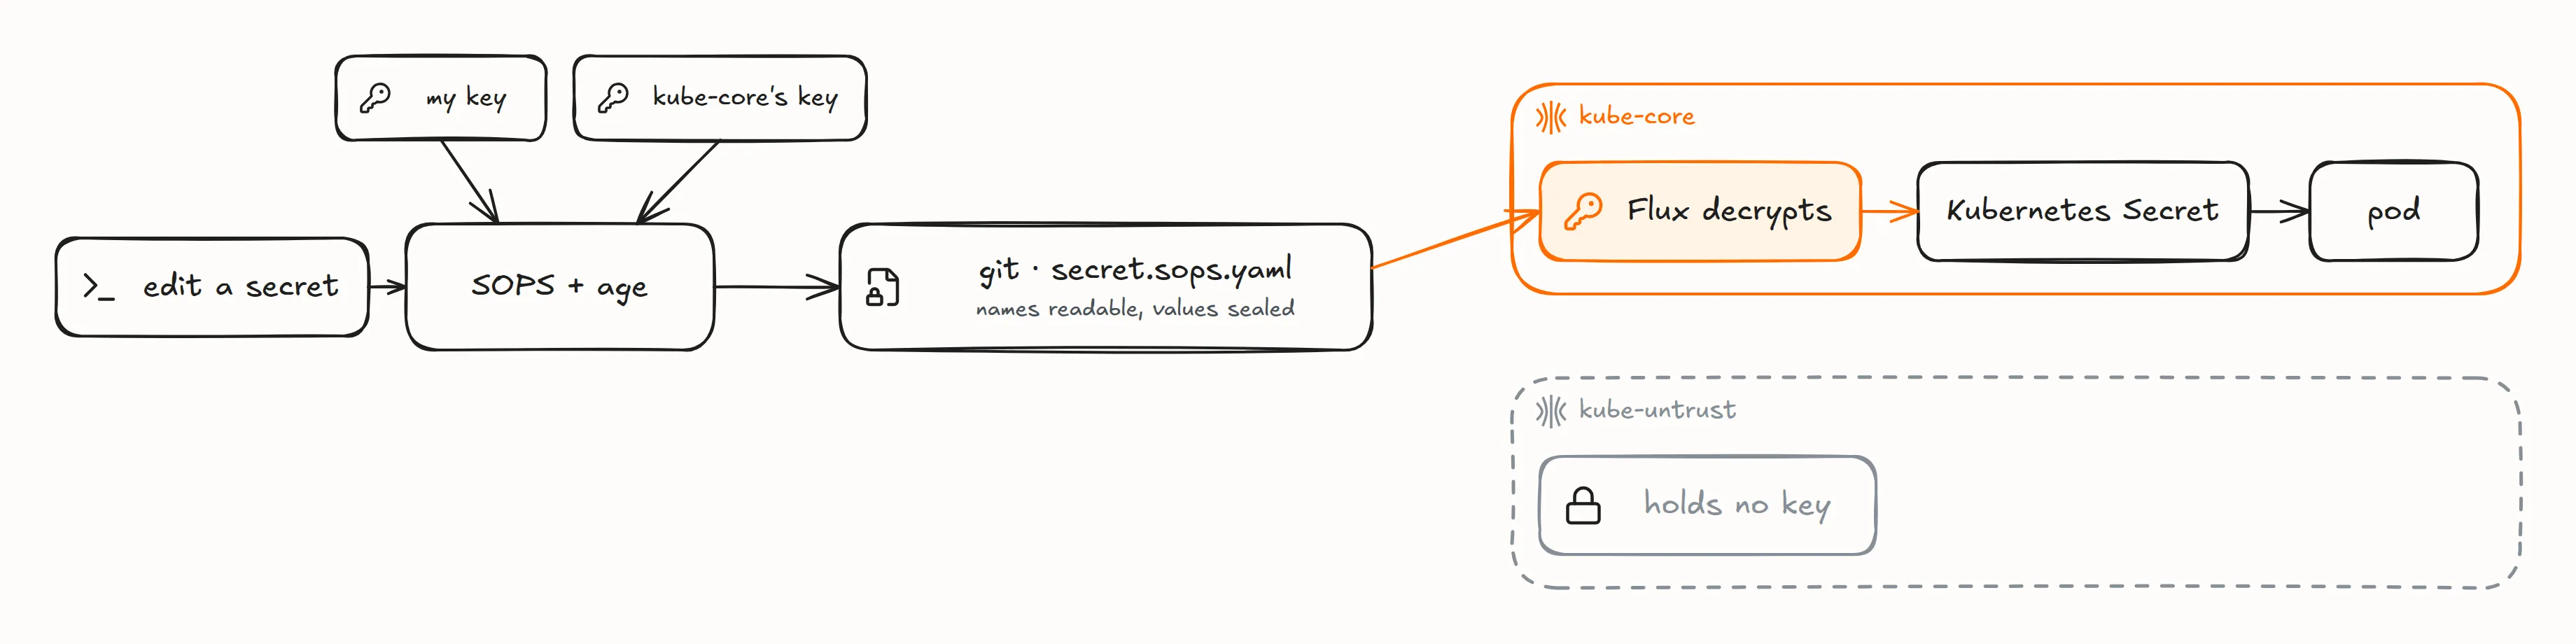
Every secret is committed. An app’s lives next to its manifests, as secret.sops.yaml. SOPS encrypts the values with age to two keys, mine and the cluster’s, and leaves the names readable, so a diff still shows which secret changed. Flux decrypts it into a Kubernetes Secret when it applies the app. kube-untrust holds no key at all. The machines outside the cluster keep their secrets in their Ansible roles, sealed the same way.
An app and its secret land in the same commit, and git log shows when a value changed. One trap: a changed Secret restarts nothing on its own, so rotating one ends with a restart of the app that reads it.
I don’t run Vault or any secret manager queried at run time. There is nothing to run, nothing to reach and nothing to unseal: the repository and one key rebuild the setup, and the backups bring back the data.
Backups go to the NAS, then off-site
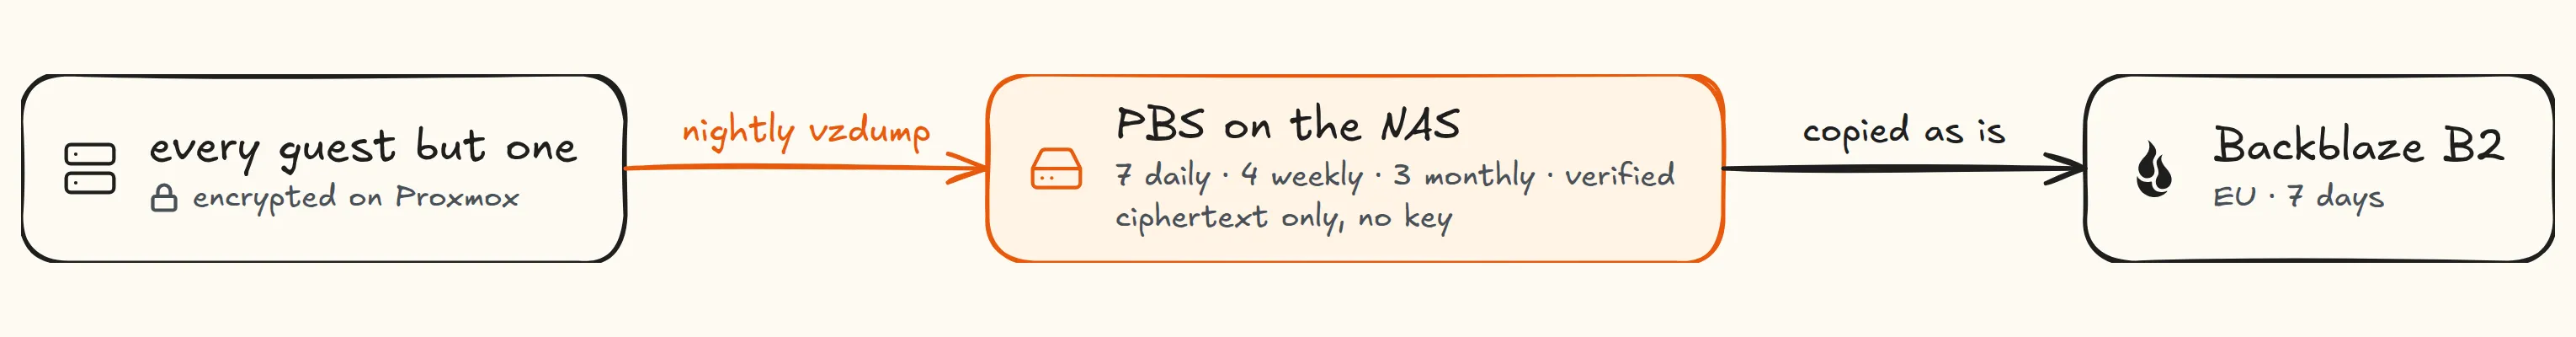
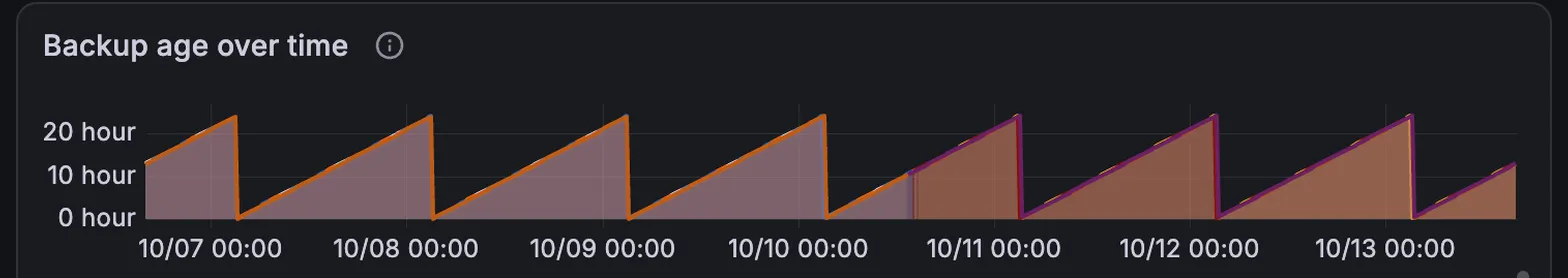
Every night, Proxmox backs up every guest but one, kept on demand, to PBS on the NAS, over the LAN. Proxmox encrypts each backup before it leaves the host, so PBS only ever stores ciphertext and holds no key. PBS keeps 7 daily, 4 weekly and 3 monthly backups and verifies them. It then copies those encrypted backups as they are to Backblaze B2 in the EU, kept seven days, for the day I lose the whole site, and refuses to send one that isn’t encrypted. The B2 key that writes that copy can’t erase it at once: a delete only hides a file, which stays recoverable for seven days before it is gone. A single encryption key, also kept in my password manager, reads both copies.
The cluster needs nothing special here. Every persistent volume is a directory on its node’s data disk, so it leaves with the VM’s nightly backup. Media aren’t in the cluster at all: downloads land on a share on the NAS, and the music and films live there too, read by Navidrome and Jellyfin. The lab uses the NAS as storage and doesn’t back it up.
One gotcha worth knowing: Proxmox backups don’t keep a guest’s snapshots, and nothing warns you.
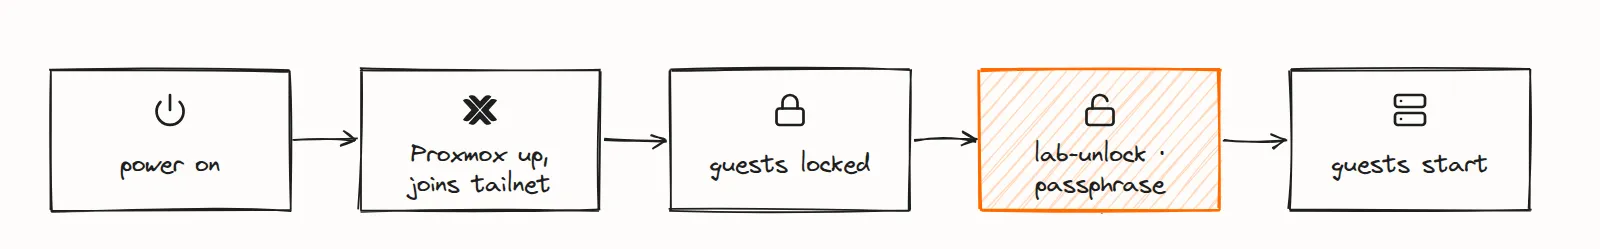
On the hypervisor, the guests live in encrypted LUKS2 volumes. Proxmox itself boots, joins the tailnet and, after a power-on, waits for me to unlock them. A plain reboot doesn’t ask: Proxmox jumps straight into the next kernel with kexec, carrying the volume keys over in RAM, never on disk, and the guests come back on their own.
Monitoring
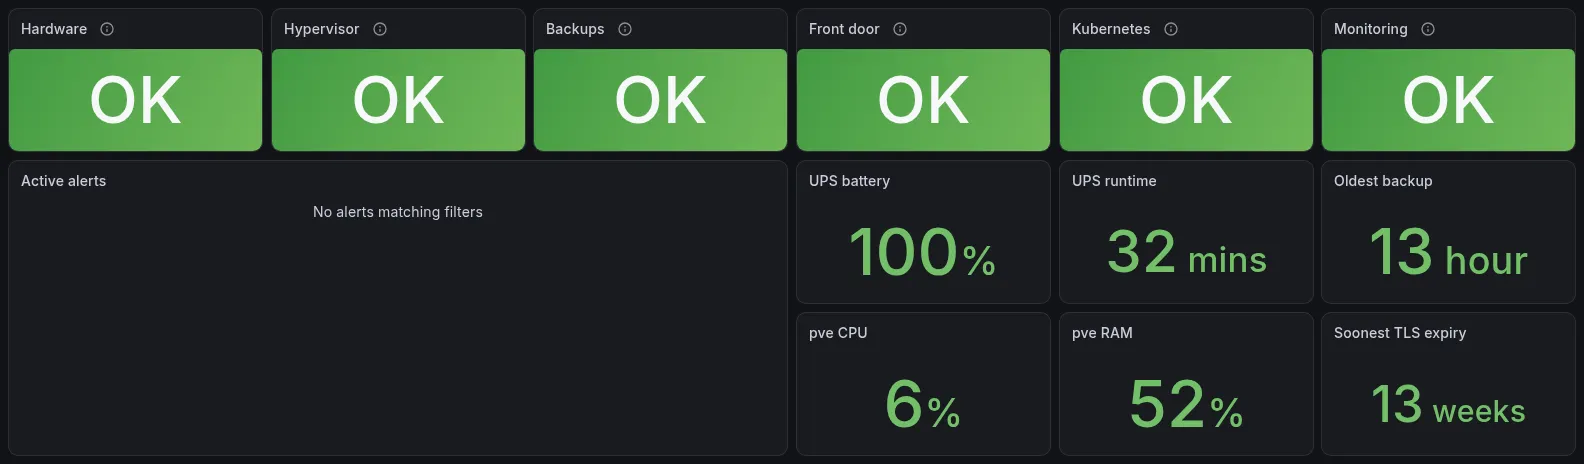
Prometheus, Loki and Grafana run in the cluster, in a namespace of their own. Loki gets the pods’ logs and also kube-core’s Talos service and kernel logs, since there is no shell to read them from. The dashboards are filed by layer, hardware, hypervisor, backups, front door, Kubernetes and logs, and the home dashboard has one tile per layer counting its problems, green at zero.
Alerts go out by email through Cloudflare’s Email Sending API, so their delivery doesn’t depend on the lab. The monitoring can’t report the death of the node it runs on, so a watchdog on the DNS guest probes the cluster through Traefik and mails me when kube-core stops answering.
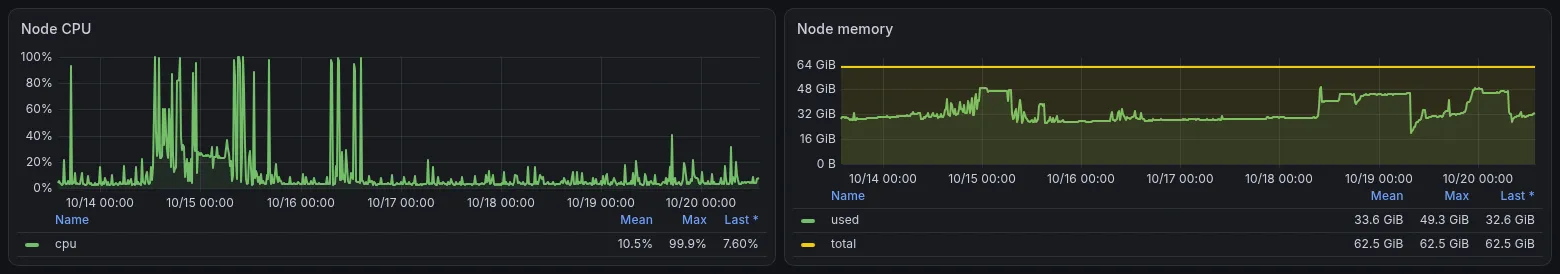
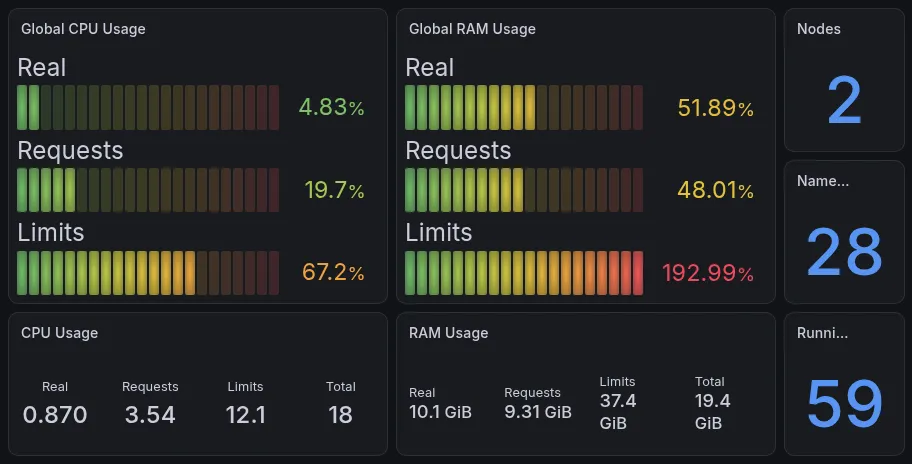
The whole cluster, about sixty pods, uses less than one of the 18 vCPUs its two nodes have, and about 10 GiB of memory.
A tip if you run node-exporter in an LXC: it reports the host’s numbers as its own, because /proc is partly faked by lxcfs and /sys isn’t namespaced. Disable its host-reading collectors and let the hypervisor publish those metrics. A VM has its own kernel and keeps every collector.
What I accept
My target is to lose at most 24 hours of data, and to recover in hours from a software problem or in days from a hardware one. There is no uptime promise. That is why there is no RAID and no high availability: the contract doesn’t call for either.
The rest follows from having one box. If the hypervisor dies, the watchers die with it and nothing tells me. And when the rack is down, my Mac is a laptop with nothing to work on.
The agents on those dev boxes also write the lab itself, in sessions I supervise, and I read each change before it lands. That is its own post.
Discussion on r/homelab.
Icons in the diagrams: Simple Icons (CC0) and Lucide (ISC).